Korea University
Signal Processing
GAN
TTS
Computer Vision
Education
- 전체평점: 4.13 / 4.5 (총 24 학점)
- Overall GPA: 4.13 / 4.5 (24 credits total)
ISPL: Intelligent Signal Processing Laboratory 2020.11 ~ 2022.12 지도교수 고한석 ISPL: Intelligent Signal Processing Laboratory 2020.11 ~ 2022.12 Advisor: Prof. Hanseok Ko
졸업 논문: Deep Learning Framework Design via Condition Guided Learning (Paper) M.S. thesis: Deep Learning Framework Design via Condition Guided Learning (Paper)
Projects
프로젝트를 선택하면 아래에 상세 내용이 표시됩니다 Select a project to view its details below
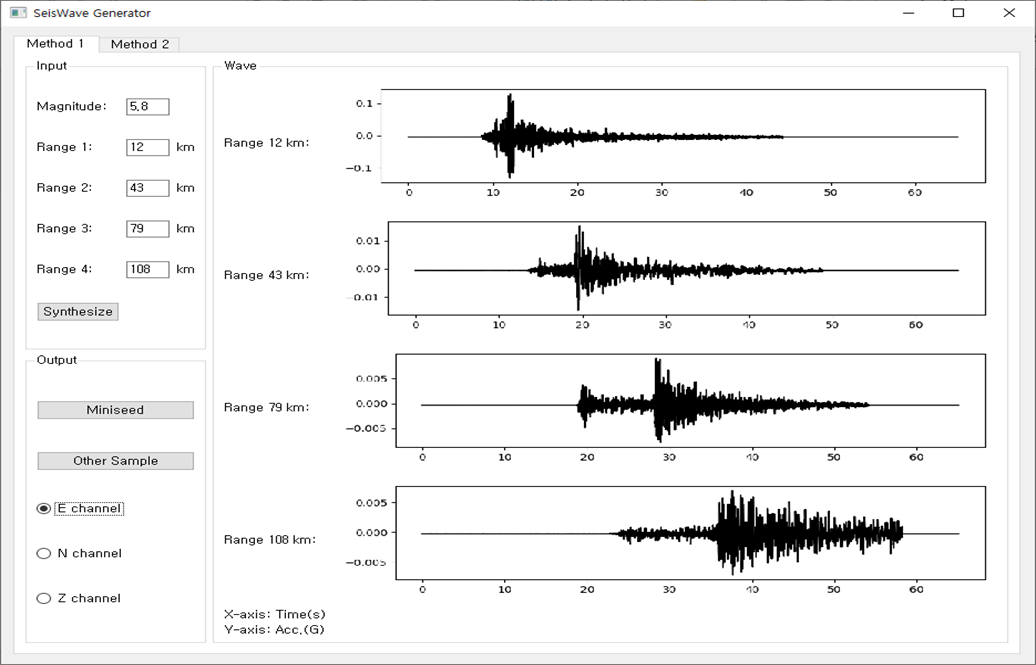
인공지능 기술을 활용한 가상의 한반도 지진 시나리오 생성 기법 연구 (기상청 연구용역, 2021) AI-based Generation of Virtual Earthquake Scenarios on the Korean Peninsula (Research project commissioned by the Korea Meteorological Administration (KMA), 2021)
연구 필요성Motivation
- 2000년 이후 한반도 내 규모 5.0 이상 지진 발생, 추가 가능성 경고
- 국내 규모 3.0 이상 지진 빈도가 낮아 분석 시스템 검증 한계
- Since 2000, magnitude 5.0+ earthquakes have occurred on the Korean Peninsula, with warnings of further events
- Low frequency of M3.0+ events in Korea limits validation of analysis systems
연구 목표Objectives
- GAN 기반 규모 3.0 이상의 지진 데이터 생성 기술 개발
- 메타데이터를 이용한 가상 지진 시나리오 소프트웨어 개발
- Develop GAN-based generation of M3.0+ synthetic earthquake data
- Develop software that uses metadata to compose virtual earthquake scenarios
담당 업무Responsibilities
- 생성 모델 학습을 위한 지진 데이터셋 구축
- 생성된 지진파 검증 알고리즘 구현
- 지진 시나리오 소프트웨어 제작 및 유지보수
- Built the earthquake dataset used to train the generative model
- Implemented an algorithm for validating generated waveforms
- Developed and maintained the earthquake-scenario software
연구 성과Results
- 지진 시나리오 소프트웨어 기상청 배포 및 유지보수
- Delivered and maintained the earthquake-scenario software for the Korea Meteorological Administration
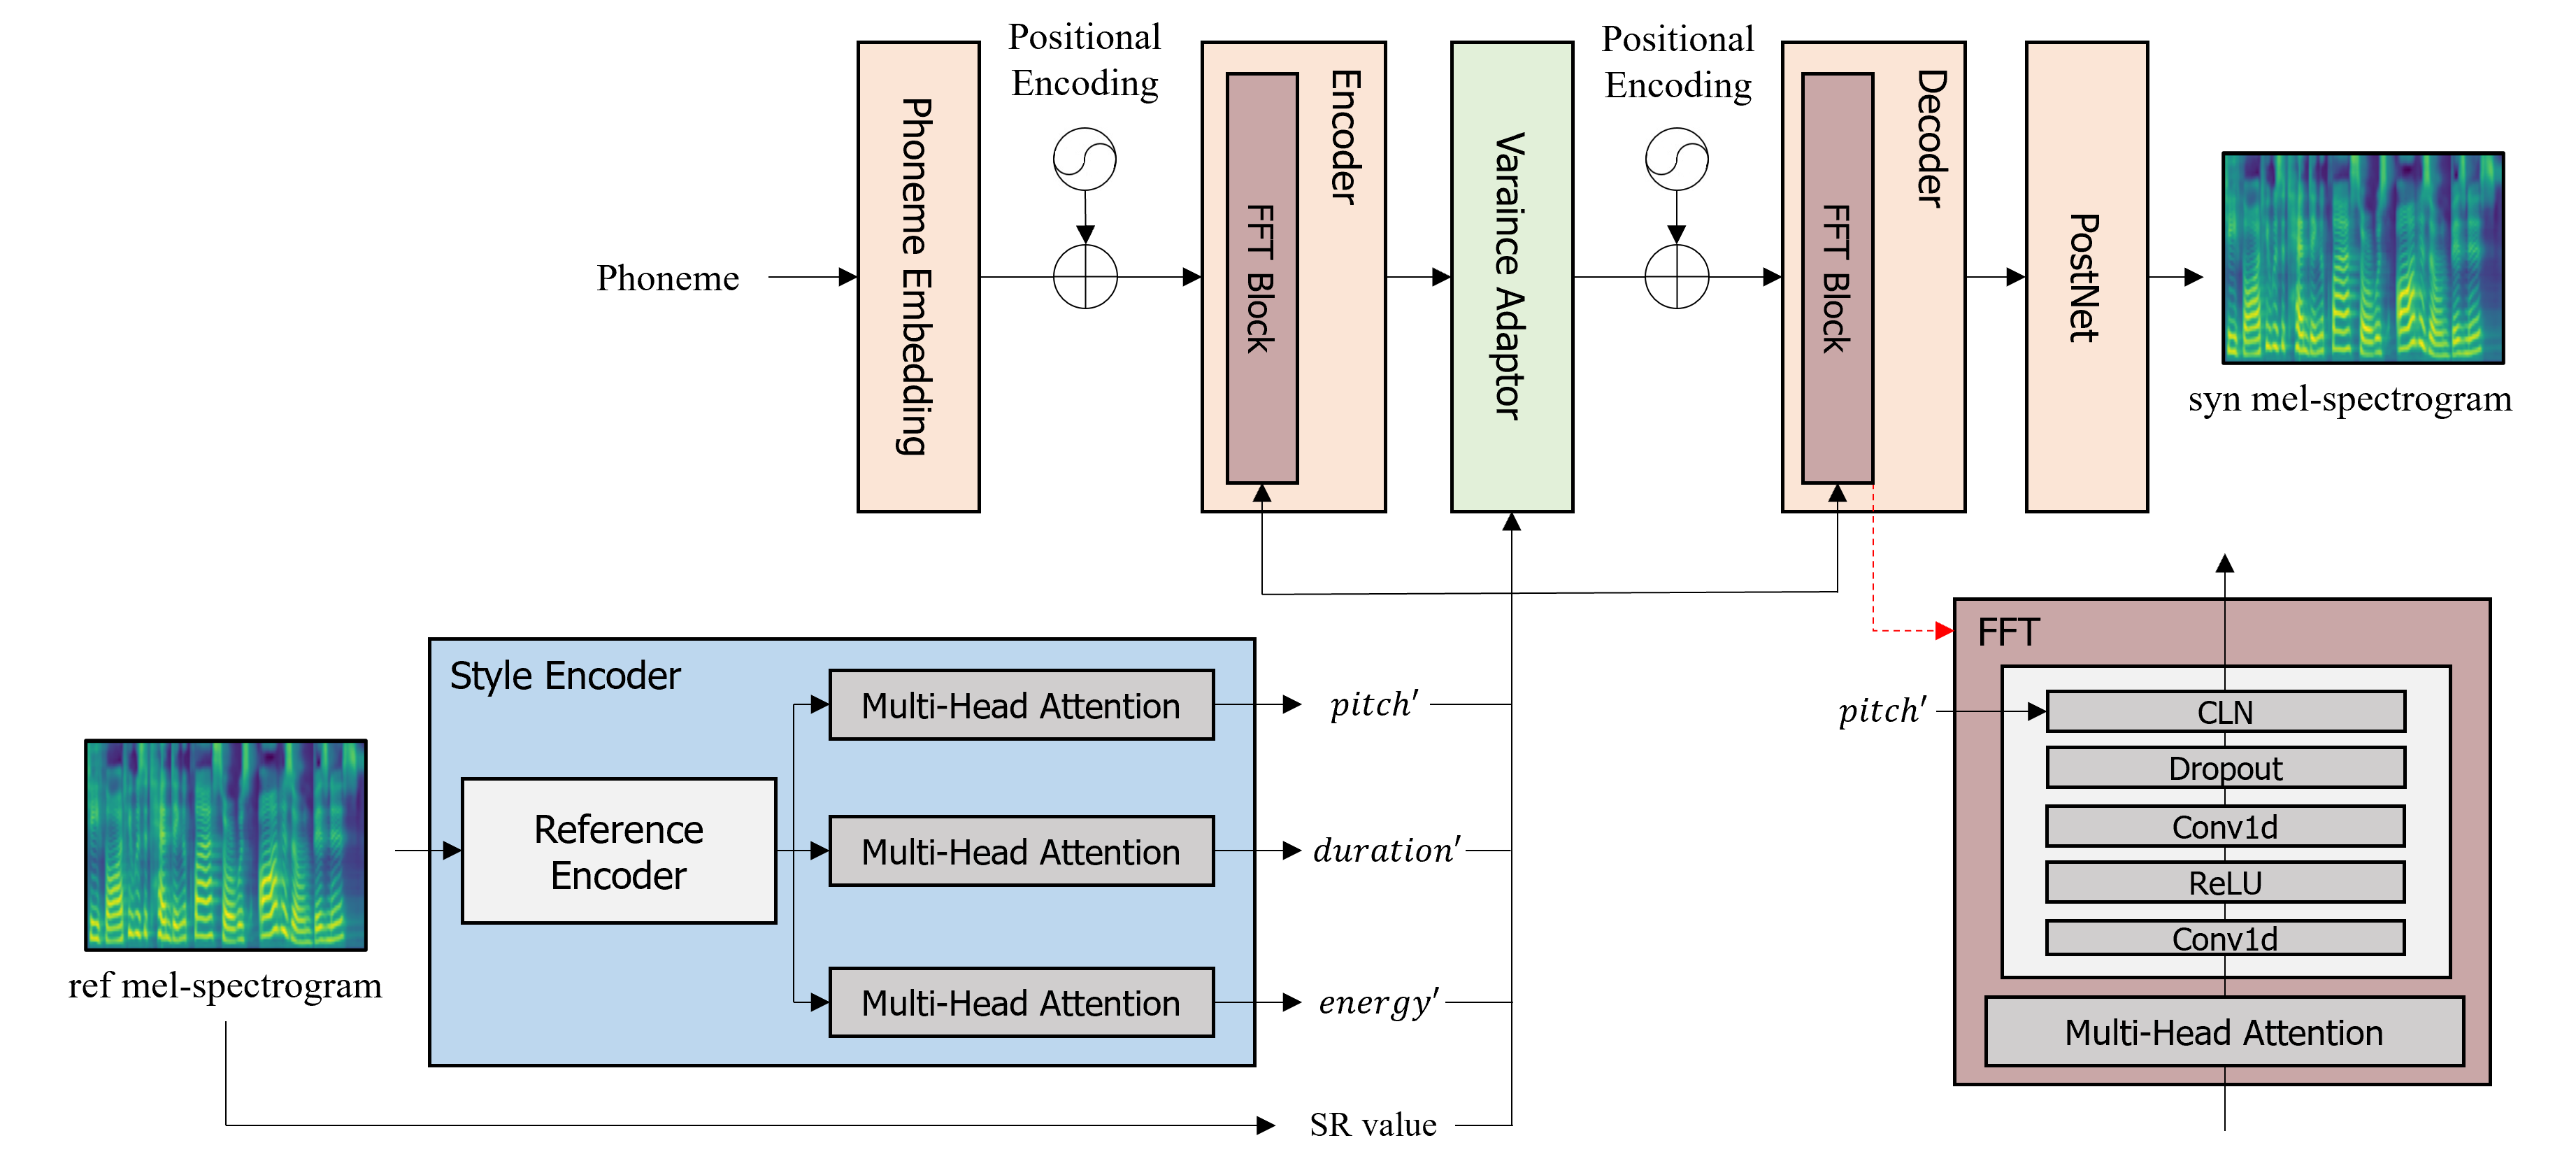
낭독체 및 대화체 음성 합성 모델 개발 연구 (Deep Machine LAB, 2022) Reading- and Conversational-Style TTS Model Development (Deep Machine LAB, 2022)
연구 목표Objectives
- 빠른 추론이 가능한 음성 합성(Text-to-Speech) 알고리즘 설계
- 다중 화자 음성 합성을 위한 모델 구조 연구
- 운율 및 감정 제어 TTS 모델 연구
- 발화 시간 및 피치 조절 인코더 연구
- Design a fast-inference text-to-speech algorithm
- Study model architectures for multi-speaker synthesis
- Investigate TTS models with prosody and emotion control
- Investigate duration and pitch control encoders
담당 업무Responsibilities
- 화자 및 감정별 음성 데이터셋 구축 및 전처리 파이프라인 개발
- 참조 오디오 기반의 감정 제어 음성 합성 모델 제안
- Built the speaker- and emotion-labelled speech dataset and the preprocessing pipeline
- Proposed a reference-audio-based TTS model with emotion control
연구 성과Results
- 낭독 및 대화체 통합 TTS 프로토타입 구현
- MOS +5%, Similarity-MOS +11% (n = 30)
- Implemented a unified TTS prototype covering narration and dialogue styles
- MOS +5%, Similarity-MOS +11% (n = 30)
이미지 처리 연구 Image Processing Research
연구 목표Objectives
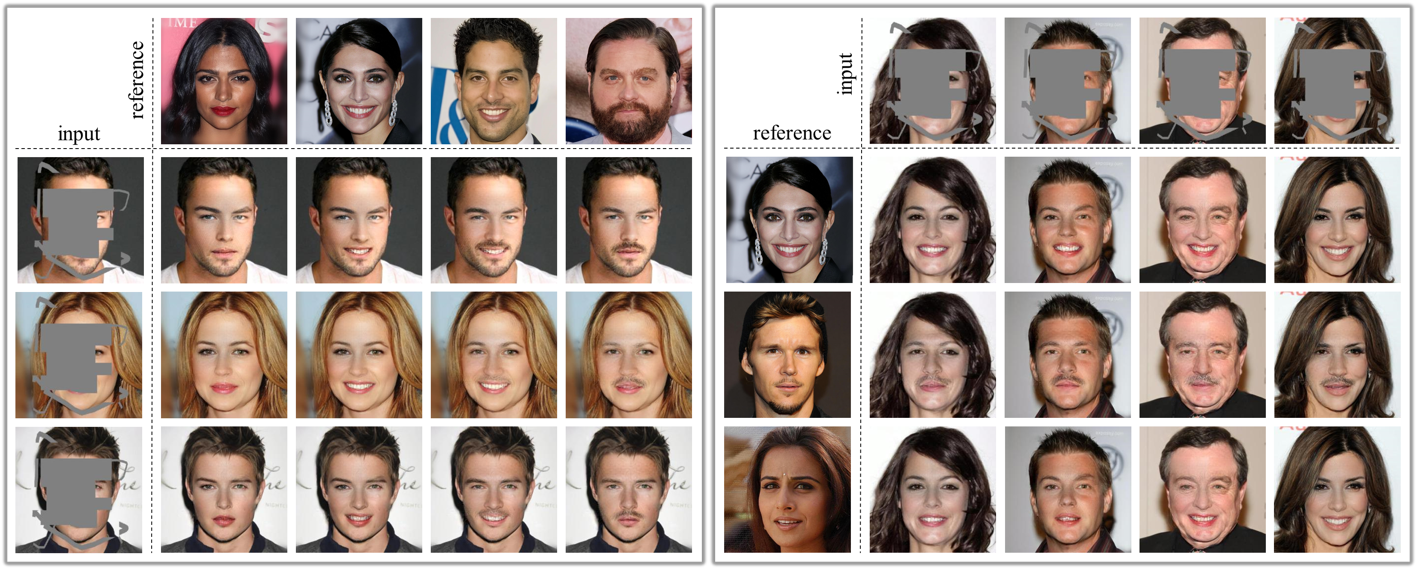
- 사용자 의도를 반영할 수 있는 참조 이미지 얼굴 속성 기반 이미지 복원 모델 제안
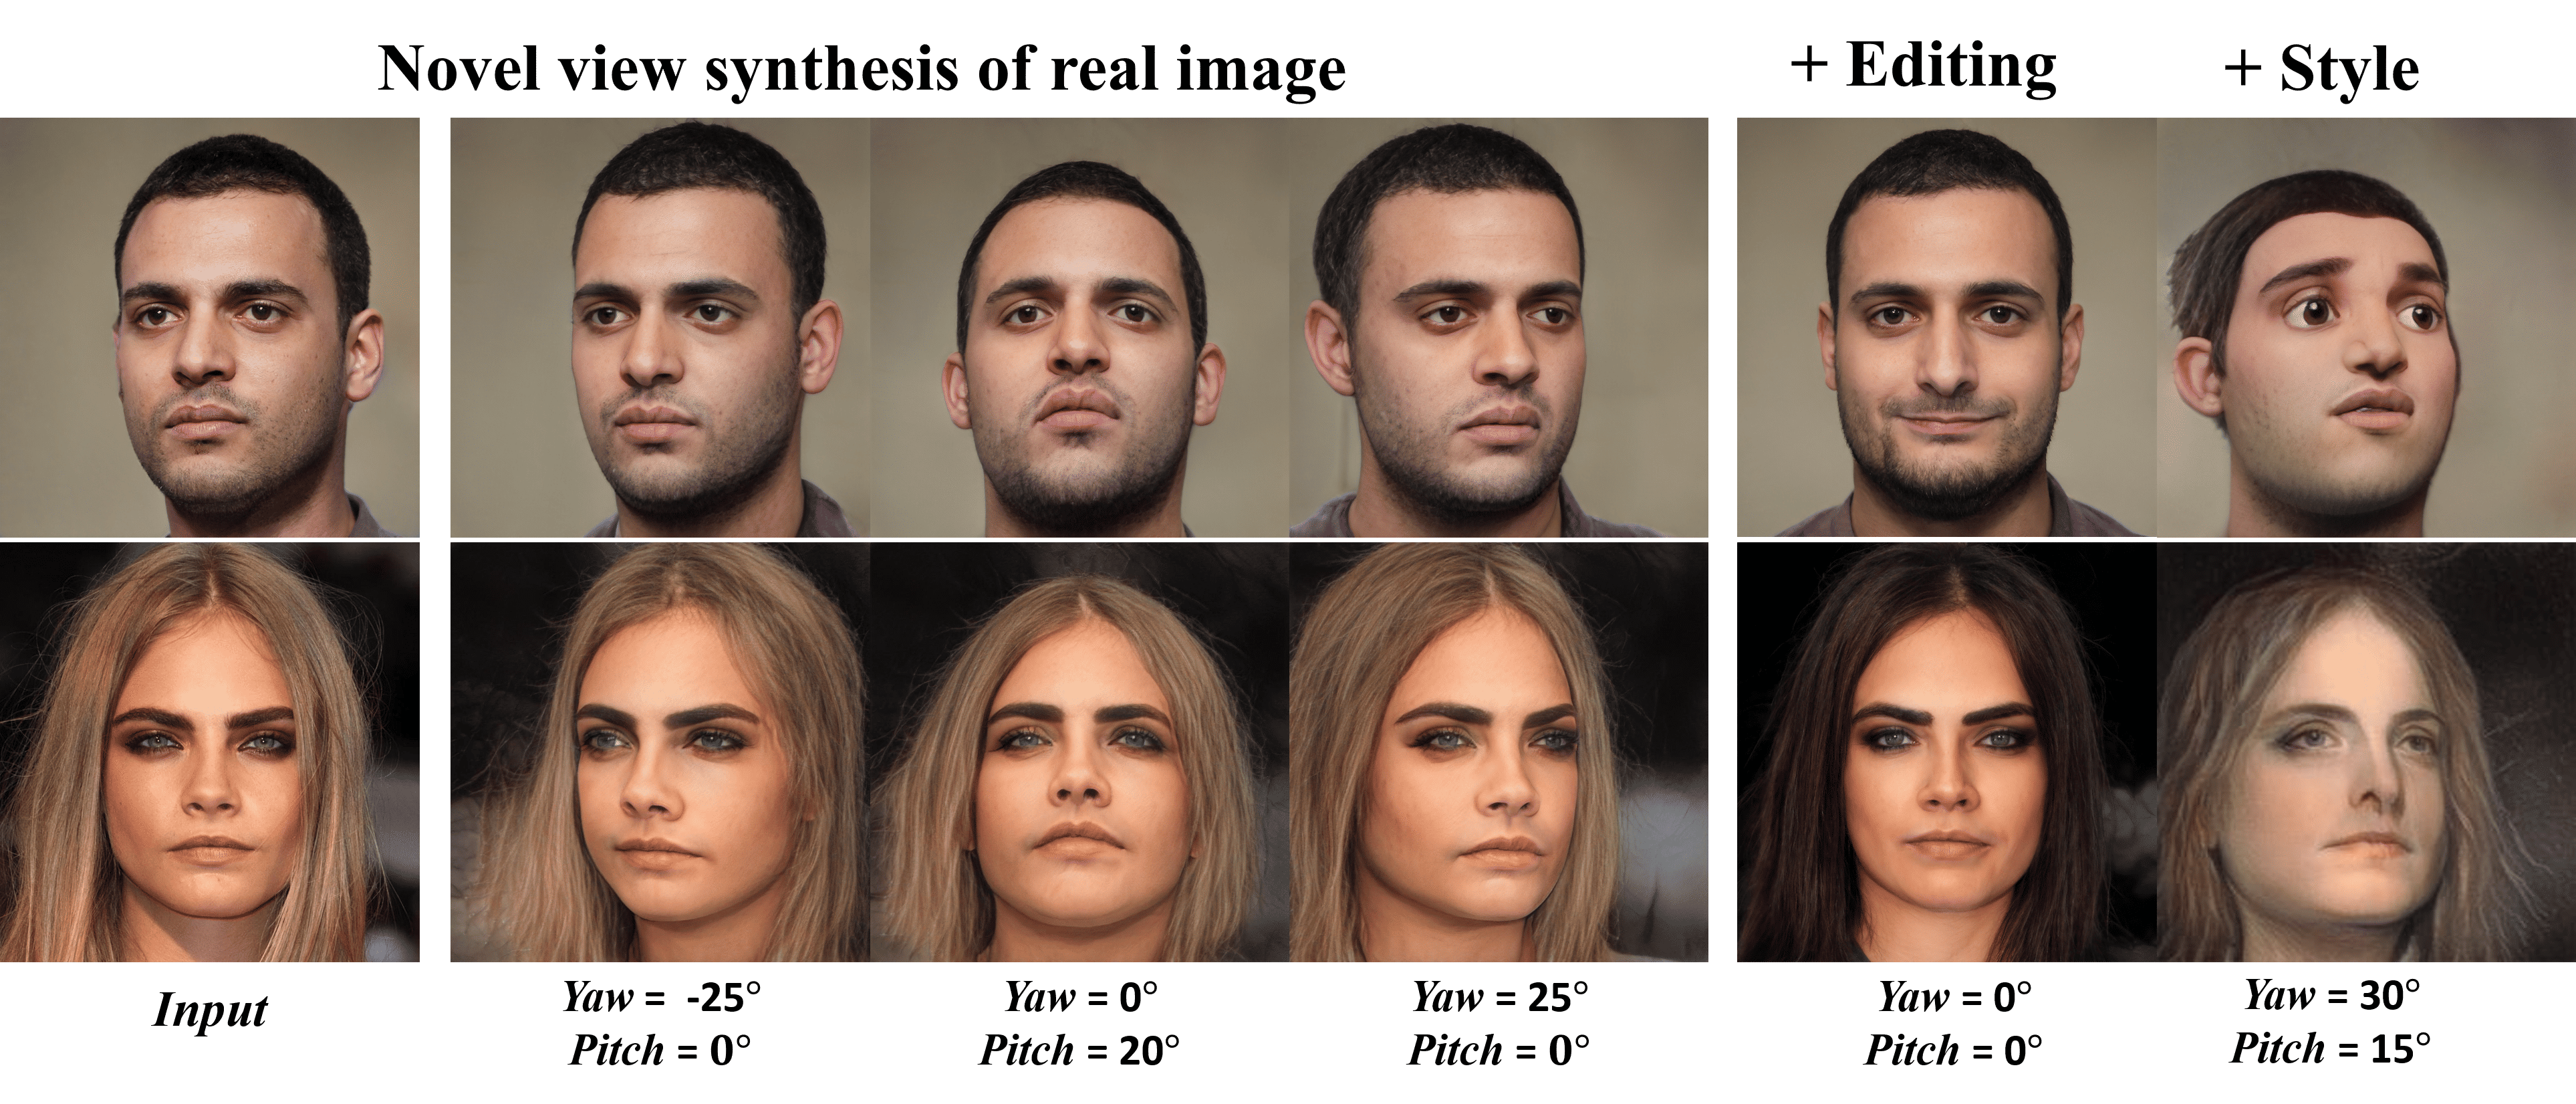
- StyleGAN 기반의 이미지 복원 및 편집 모델 제안
- 비지도학습 기반의 3D aware GAN 구조 제안
- Propose a reference-image, attribute-aware face inpainting model that reflects user intent
- Propose StyleGAN-based image inpainting and editing models
- Propose an unsupervised 3D-aware GAN architecture
담당 업무Responsibilities
- 박사 과정 연구생들과의 CV 논문 세미나 준비
- 구체적인 연구 코드 및 결과를 보며 실험 과정 및 방향성 공유
- Co-organized computer-vision paper seminars with PhD students
- Walked through concrete code and results, sharing experimental procedures and directions
연구 성과Results